Tencent releases protein models trained by its Hyra research agent
Edited and reviewed by AI Ping Editorial Team
3-line summary
- Weights and inference code were released November 2.
- Artifacts cover protein design, sequence analysis and molecular simulation.
- Reported speeds are Tencent measurements under stated H20 test conditions.

Tencent Hunyuan has released weights and inference code for protein models trained by its Hyra 2.0 research agent. Its official research repository records the releases on November 2, alongside a family of models for molecular simulation.
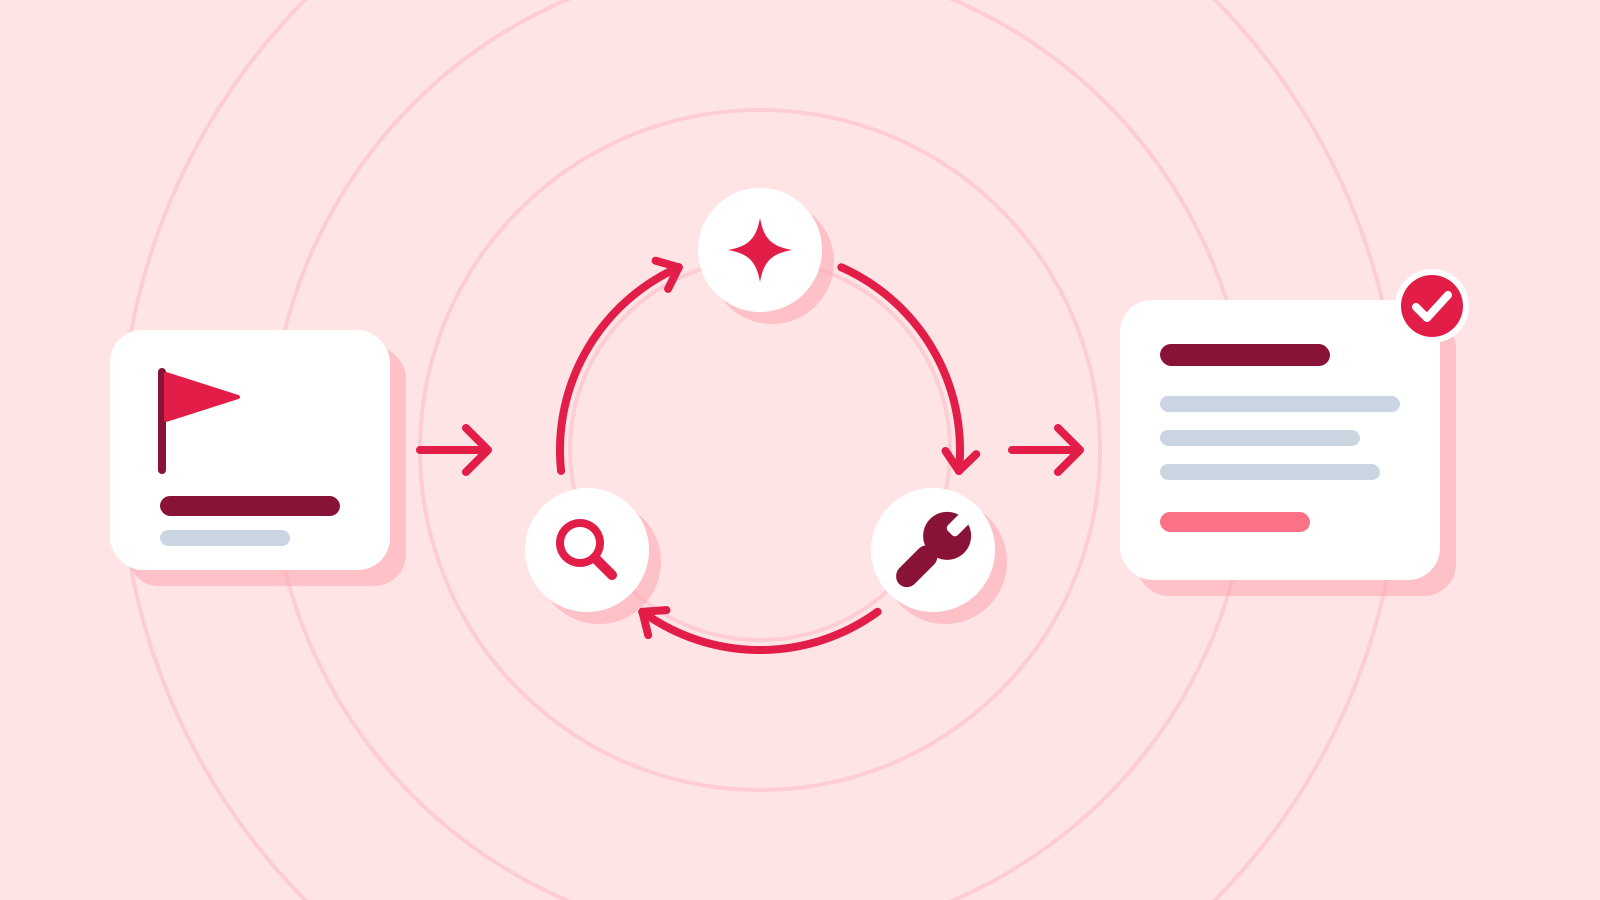
Researchers can download the artifacts and apply them to their own structures, sequences and molecular systems. Tencent describes preserving code versions and experiment records during the agent’s work, with separate review of conclusions. Substantial compute expenditure requires human approval.
HyInv generates candidate amino-acid sequences for a specified protein backbone, supporting the preparation of libraries for screening. The roughly 1.96-million-parameter model has a 7.8MB weights file and runs on CPUs or GPUs. Selected positions can be held fixed while the remaining sequence is designed.
Its technical report, dated October 14, describes drafting candidates and then revising groups of positions. Reinforcement learning rewards agreement between a candidate’s predicted structure and the target backbone. The report says design-time inference uses the backbone alone, without an additional protein language model or structure predictor. Evaluation compares structural consistency alongside sequence diversity; the consistency score uses structures folded by prediction models.

Tencent reports generating 128 candidates for a 402-residue backbone in 50.6 milliseconds on one H20 GPU. A residue is an amino-acid unit in the chain. That accelerated result excludes compilation and execution preparation. The released instructions say the fast numerical path can produce different sequences from the reference implementation under the same random seed.
The second protein model, HyPLM-Flash, learns by reconstructing masked parts of sequences. Its roughly 650 million parameters support mutation scoring and extracting numerical representations of proteins. The October 12 report gives training volume as 726 billion tokens, 0.73 times that of ESM-2 650M. In Tencent’s matched evaluation of 28 public checkpoints, its mutation-effect correlation was statistically tied with leading encoders of similar size.
Tencent says HyPLM’s inference engine processes about 130,000 residues per second on one H20. It accepts sequences of up to 8,190 residues and requires a CUDA GPU environment. Its 2.6GB weights are distributed in shards. Outputs include per-residue vectors and pooled representations of a sequence. INT8 is the default precision; the instructions recommend BF16 when training downstream predictors on nearly identical protein variants.
The accompanying HyFF models predict energy and atomic forces from atomic species and coordinates for molecular dynamics. Five sizes span 2.3 million to 1.2 billion parameters and cover 83 elements, with total charge and spin supplied as inputs. They are trained on the OMol25 quantum-chemistry dataset, offering different tradeoffs between accuracy and computation time.

HyFF’s October 29 report compares accuracy on roughly 2.76 million validation structures and times a 2,586-atom simulation on one H20. Tencent reports comparable force error to UMA-S-1.2 for its Andante model at 29 times the speed in that test. The execution documentation says other GPUs remain untested. CPUs support single-structure inference; molecular dynamics and accelerated engines require Linux, an NVIDIA GPU and CUDA. Simulations support temperature and pressure controls and save timing, energy traces and final coordinates.
Both protein packages carry MIT licenses, while HyFF uses Apache 2.0. HyFF weights are separate downloads, fetched and checked against file hashes on first use. The reports carry October writing dates; the repository records the weights-and-code releases on November 2.
Sources
- Hyra 2.0: The Next Step for Auto Research — Tencent Hunyuan
- November 2 model-release records — Tencent Hunyuan
- HyInv released inference documentation — Tencent Hunyuan
- HyInv Technical Report — October 14, 2026 — Hyra Team
- HyPLM-Flash released inference documentation — Tencent Hunyuan
- HyPLM Technical Report — October 12, 2026 — Hyra Team
- HyFF released execution documentation — Tencent Hunyuan
- HyFF Technical Report — October 29, 2026 — Hyra Team
- HyPLM weights release — November 2, 2026 — Tencent Hunyuan
- HyFF model weights release — November 2, 2026 — Tencent Hunyuan