What is an AI agent?
Unlike a chatbot that only answers, an agent takes a goal and keeps going, using tools and checking results, until the job is done. How it works, what it suits, and what to settle before you hand it work.
About 17 min readingAs of Oct 2026
Lesson guide · goals & preparation
By the end of this guide
- Explain the difference between a chatbot, a fixed workflow and an agent.
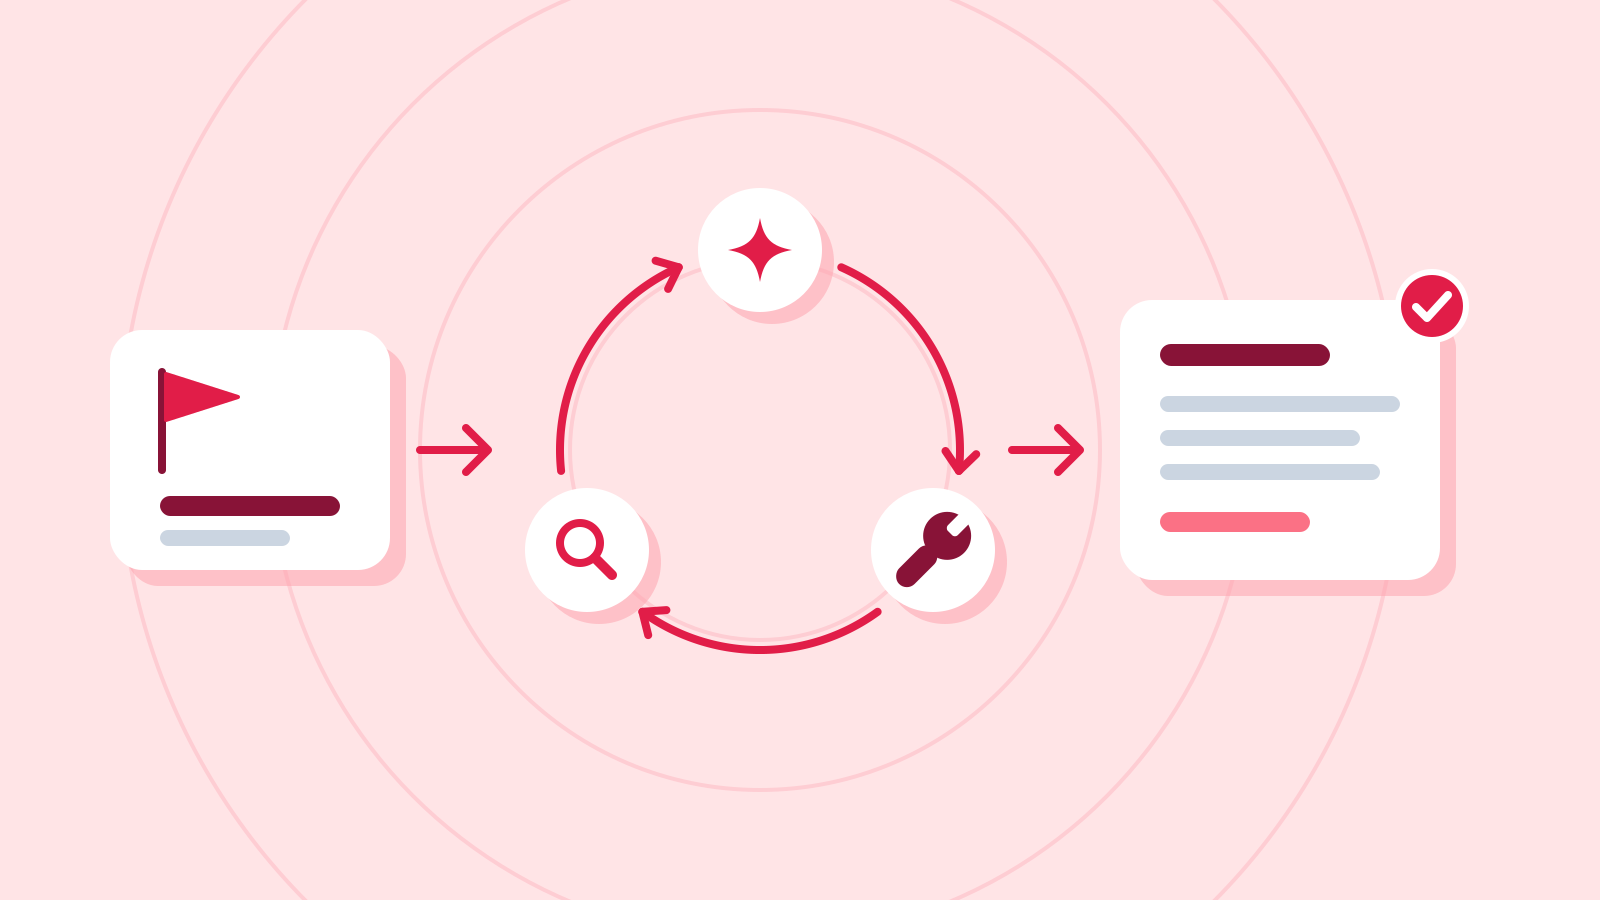
- Understand how an agent works by repeating a loop: decide, use a tool, check the result.
- Check permissions, approval steps and stopping conditions before handing work to an agent.
Who this is for
- Anyone who keeps seeing "agents" in AI news and launches and wants to know what it really means
- Anyone weighing AI agents for their team's work
What you need
- Reading "What is an LLM?" first will help.
This lesson’s terms, in plain language
Read the short meanings here. Open a term for a fuller explanation and example.
This reading lesson explains how to use external AI tools. Read from theory to the workflow, examples and explanations, or use the contents to jump to a section.
1 / 4
Theory
Understand what to ask AI to do, how to ask, and the ideas behind the workflow.
From answering to doing
Suppose you ask why refunds increased. A ready-made aggregate may need only one summary. Scattered evidence may require queries, classification and calculations in an adaptive order. We will rehearse that investigation with fictional data.
Products use “agent” differently. Here it means a configuration in which a model chooses subsequent steps and tools, contrasted with a predefined workflow. Real systems may combine both.
A goal does not grant unlimited tool permissions. Investigating refunds is different from issuing them. Define readable aggregates, writable files and permitted communications separately; plans must stay inside that scope.
Chatbot, workflow and agent compared Approach Who decides the next step Example Chatbot A person, one question at a time Paste in meeting notes and get a summary Workflow A developer, in a fixed order A message arrives → classify → draft a reply → staff review Agent The LLM, step by step as results come in To find why refunds rose, it queries data, calculates, then queries again It loops: decide, use a tool, check
Inside, an agent is usually simple. The LLM looks at the goal and picks a tool and its inputs; the app or service runs the tool and returns the result. The LLM reads the result, decides the next step, and repeats until the goal is met.
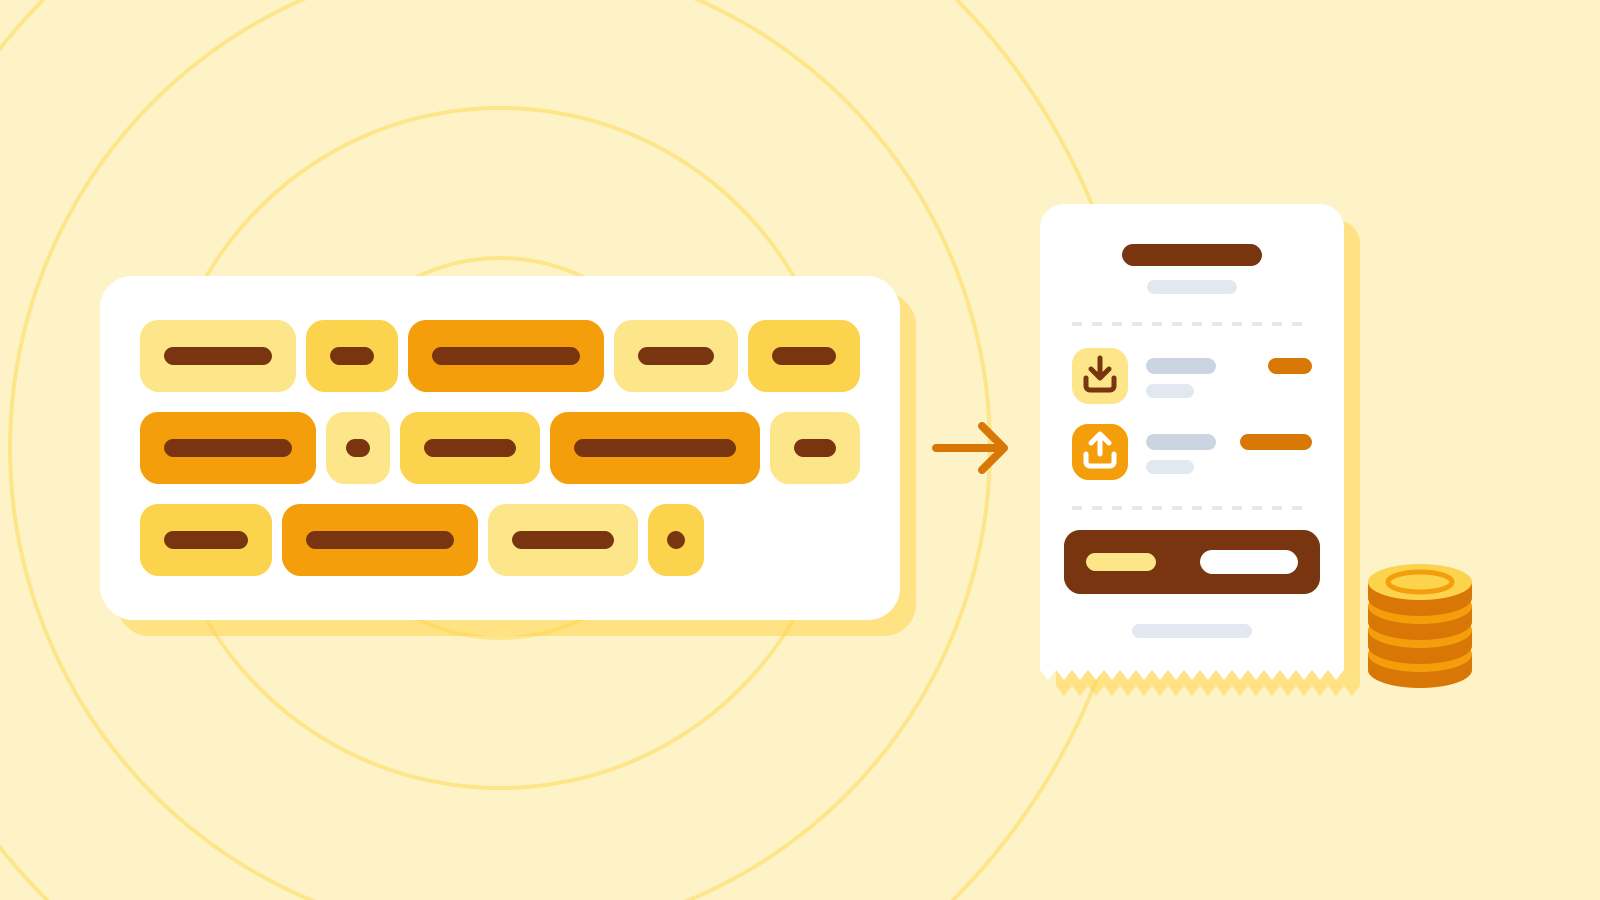
Figure: A decision note followed by a tool-result document · AI Ping Tools are capabilities wired in ahead of time: search, database queries, reading files, calculations, drafting an email. Because it sees a real result at every step, it can change course midway when the first plan turns out wrong.
For a fictional calculation, a tool receives 30 and 20 and returns a 50% increase. Correct arithmetic does not establish that both counts cover comparable periods and definitions. Tool success is not evidence that its inputs were appropriate.
An agent working on "Tell me whether refund requests rose this month compared with last month" (example) Step The LLM decides Tool used Result 1 Start with this month's messages Query the support database (October) 412 messages 2 Count only the refund requests Tally by category 57 refund requests 3 Last month's figure is needed to compare Query the support database (September refunds) 41 refund requests 4 Ready to answer (no tool) "57, up 16 from 41 last month" Check it
- When you use an agent-based service, check that it shows a step-by-step log of which tool it used with which inputs. Without one, you can't tell at which step a wrong result crept in.
2 / 4
Step-by-step use
Learn what to prepare, how to request help and how to revise the result through examples and explanations.
Good fits, and jobs it isn't ready for
Agents suit work where you can't predict how many steps it will take or fix the order in advance. In exchange, every extra step adds time and cost, and a small mistake early on can carry through to the end.
So start with the simplest approach that works. If one request does the job, use a chatbot; if the steps are always the same, a workflow is enough.
Start with a workflow when the order is stable. A weekly sum of fixed columns has a clear deterministic solution; using AI does not require inventing a new plan every time. Adaptive selection can help when each finding changes the next useful question.
Matching the approach to the job Kind of job Best fit Why Answering one question, summarizing, translating Chatbot (one request) One step, so no agent needed Repetitive work that always runs in the same order Workflow A fixed order is cheaper and more predictable Research or fixes where the number of steps is unknown Agent The next step depends on each result Hard-to-undo actions (payments, mass deletion) A person does it, or a person must approve A small misjudgment would be carried out as is Example prompt I want to pick which of my team's tasks suit an agent. For each of the three below, tell me in a table whether it fits 'one request', 'a fixed workflow' or 'an agent', and why. 1) Building the weekly sales report every Monday, always in the same format 2) Finding out why customer complaints suddenly went up 3) Translating a one-page contract from English
Worked example & explanation These are editorial design judgments. A task with the same name may need a simpler method depending on evidence and permissions.
The best fit for each task (example) Task Best fit Why Weekly sales report Fixed workflow The same data is gathered in the same order into the same format each week, so the steps can be set in advance Why complaints went up Agent There's no telling in advance which data to check, or how many times Contract translation One request It's a single step, but check your company's security rules before pasting in a contract Settle these first: permissions, approval, stopping
Because an agent carries out several steps on its own, the damage from a mistake, or from being tricked, can grow just as much. Run it thoroughly in a test environment first, and connect it to real work only after settling the four points below.
Agents that read web pages, emails or documents can be fooled by instructions hidden inside them. This is called prompt injection, and attackers use it to steal data or trigger unwanted actions.
“Until solved” is not a complete stop rule. For this paper exercise, stop after five tool attempts or two repeated query failures. Those are invented teaching limits, not universal safe defaults; real limits depend on cost and recoverability.
A checklist before you connect an agent Settle Why Example Minimum permissions Limits how far a mistake or an attack can reach Allow reading only at first; block writing and deleting Human approval for hard-to-undo actions Stops a small misjudgment from being carried out A person confirms before any email is sent, payment made or file deleted Stopping conditions Keeps it from looping on and running up costs A maximum number of steps, a spending cap Treat what it reads as data only So hidden instructions in web pages or emails can't steer it Don't let it follow instructions found in outside content; review its log Check it
- Start with a test account and fake data, and check the step-by-step log for what the agent did and why.
- Test that the approval step really works, and that the agent actually stops when you don't approve.
Track failure, retries and approval as states
Do not blindly repeat a failed tool call. Distinguish reads from state changes: repeating a lookup differs from repeating a refund. A delayed response does not establish that the first operation never happened.
Figure: Separating a completed record from a pending-review note · AI Ping Use states such as investigating, insufficient evidence, awaiting review and complete. Silence in a review state is not approval. Identify the exact unresolved condition, and test that rejection actually blocks execution.
Log necessary input summaries, tool names, results and output locations without indiscriminately retaining secrets or full customer records. A model’s later claim of success must agree with authoritative execution records. Open the output file to verify it exists.
3 / 4
Check & explain
Think about what you would ask AI, then read the explanation. Written submissions and external AI use are optional.
This is a learning check, not a test you must pass. Use the explanations to understand the ideas.
Q1A refund-investigation agent has an issue-refund tool. Does the goal authorize using it?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
No. Investigation and monetary action have different scopes. Stay within authorized reading, calculation and drafting; actual refunds require their own authority and process.
This is your own review, not an automatic score.
Q2The 20-to-30 comparison gives a 50% increase. Does it identify a cause?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
No. Verify comparable periods and definitions; causal claims need additional evidence. These numbers are fictional practice data.
This is your own review, not an automatic score.
Q3Can an agent proceed because nobody answered an approval request?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
Silence is not approval. Keep the action pending and state the needed decision. If a stop condition is reached, report the incomplete status accurately.
This is your own review, not an automatic score.
Common mistakes
- Building an agent for a job one request could do, adding only time and cost
- Granting write, delete and send permissions from day one
- Letting an agent follow instructions hidden in the web pages or emails it reads
Your learning record
Completion is optional. Mark this lesson when you feel ready, or move to the next lesson without marking it.
Completion is saved in this browser.
4 / 4
Apply to your work
Consider how new material changes the workflow and checking criteria. Trying an external AI tool is optional.
Try it: a five-step execution record
Draw five rows and set a fictional goal: find two pieces of evidence for increased refunds and draft a report. Allowed tools are prepared aggregates, a calculator and draft writing; customer contact, refunds and production changes are outside the task.
Record counts of 20 and 30, verify comparable periods, then calculate the increase. If the complaint-category table is missing, end with insufficient evidence instead of inventing the second reason.
The draft says counts increased 50% while category-level causes remain unverified. All numbers are invented. A partial result with explicit evidence and missing data is useful. Rehearse two repeated query failures to verify the stop rule.
Write a note (optional)
Use this only if you want to record a prompt or your understanding. This is a notebook, not a connected AI assistant.
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
References
- Building effective agents — Anthropic
- Tool use with Claude — Claude Platform Docs (Anthropic)