Evaluate AI work beyond first impressions
Build a small evaluation set, compare drafts against evidence, change one instruction and test on a fresh case. No code required.
About 18 min readingAs of Oct 2026
By the end of this guide
- Separate preferences from required behaviour in a rubric.
- Compare two drafts against source evidence and explain failures.
- Keep a final check separate from cases used for revision.
Who this is for
- You can generate a draft but struggle to choose one.
- You need teammates to judge work using the same criteria.
What you need
- Complete AI First Steps and a role course.
- Use paper or a notes app. The fictional source material and editor-written drafts below are enough for the entire exercise.
This lesson’s terms, in plain language
Read the short meanings here. Open a term for a fuller explanation and example.
- evaluation set
- Inputs, expected behaviour and evidence used to judge whether results are usable.
- prompt
- The instructions you give an AI.
- holdout evaluation
- A final check using cases kept out of the revision process.
- baseline
- The existing result or process used as the starting point for a comparison.
- workflow
- A sequence of work with conditions for moving between steps.
Step by step
A polished answer can still promise the wrong thing
Two invitations arrive. One is warm and engaging but promises free admission. The other says the fee is still being confirmed. If the notes contain no fee, this is more than a stylistic preference: the first draft creates an unsupported promise.
An evaluation set is a collection of inputs, expected behaviour and evidence for judging the result. A planner might check requirements; a designer, fixed visual properties; a salesperson, claims supported by a product brief. Judge the work, not the fluency of the assistant.
All events, drafts, numbers and scoring examples here are invented by the editor for practice. They are not model outputs or benchmark measurements. If you run your own experiment, retain its actual output and date separately, and describe the limits of this small artificial sample.
Fix the case and the rubric before comparing
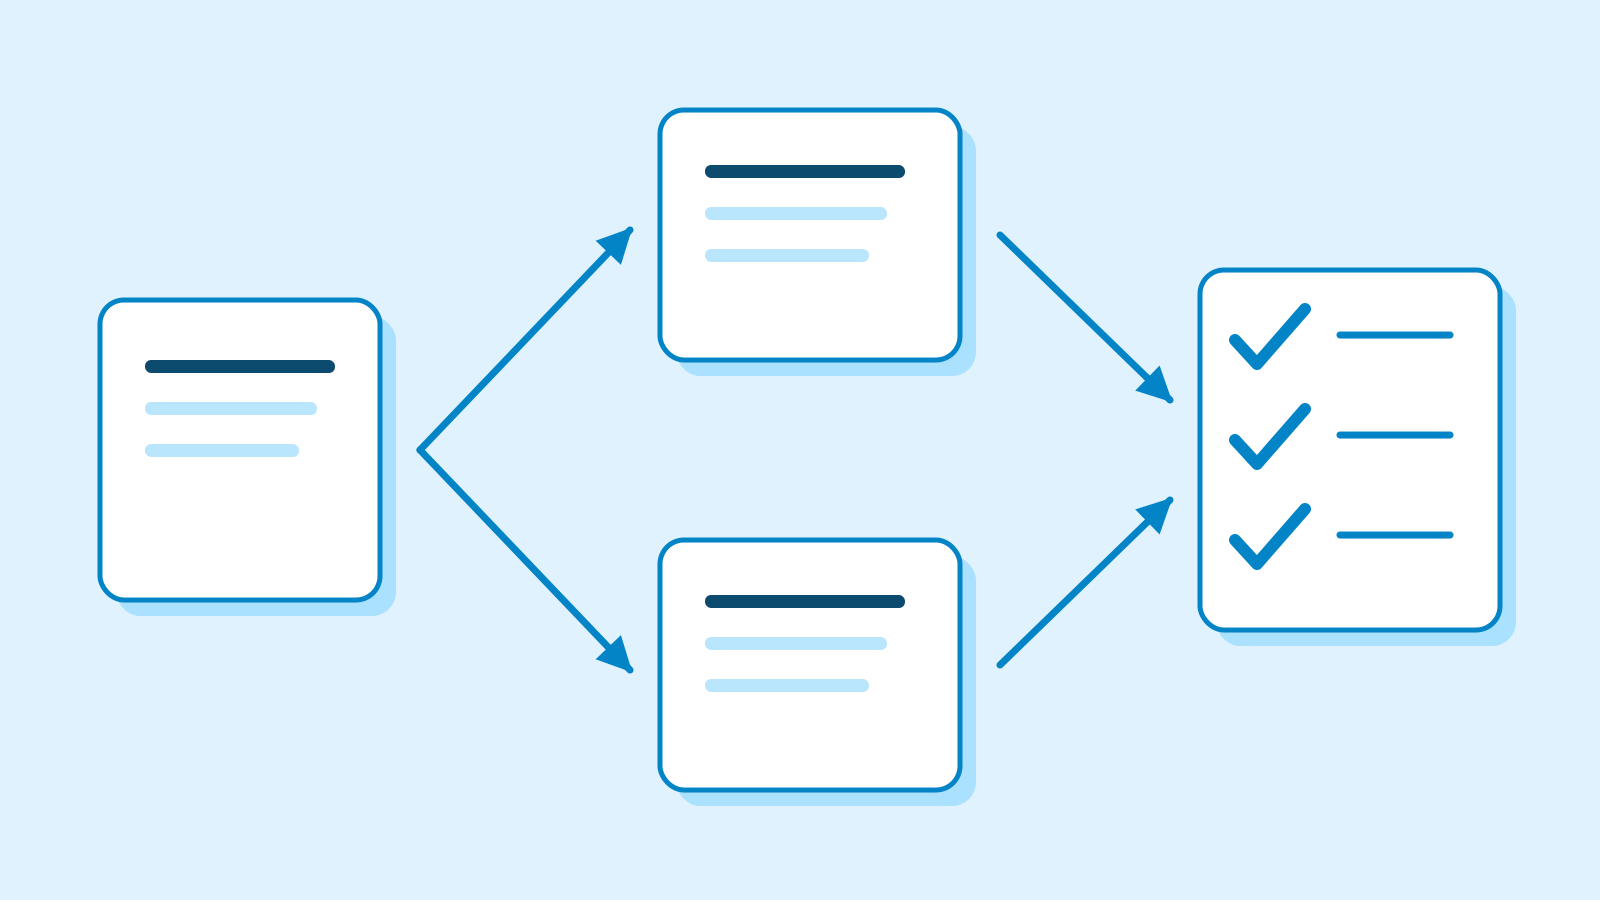
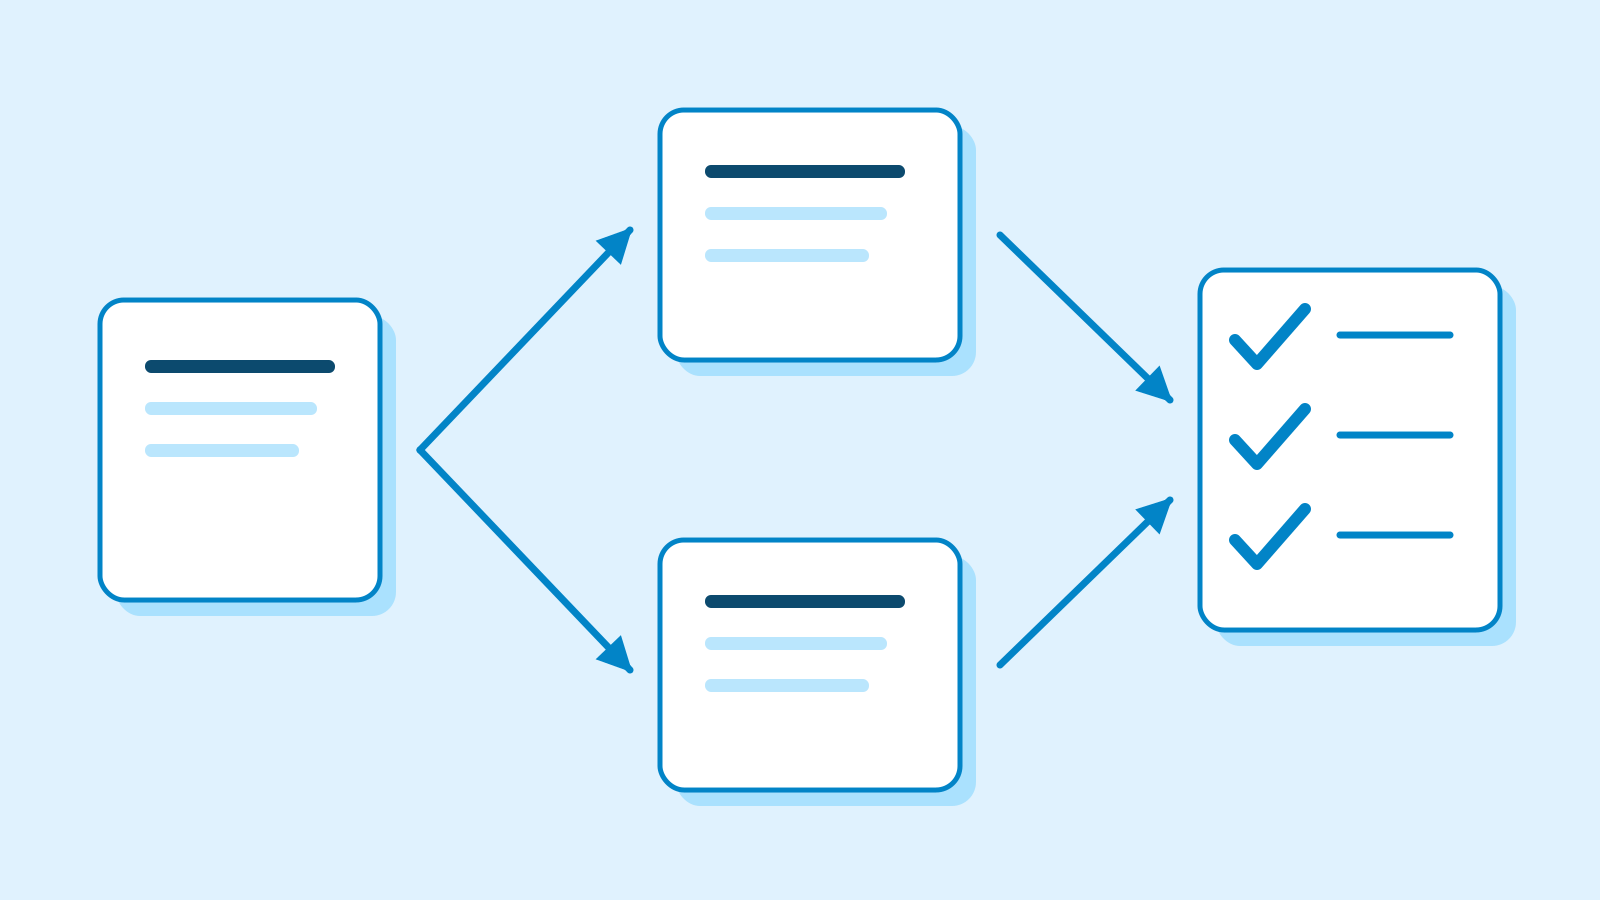
Figure: compare using the same input and criteria · AI Ping Use E1 for both drafts. Date, time, venue and what to bring are requirements. Fee and registration must remain unresolved. Warmth and brevity are preferences. A pleasant tone cannot compensate for a fabricated fee.
Replace 'accuracy: five points' with observable checks: retain all four supplied facts; do not settle the two unknowns; make the preparation clear. Mark each check as pass or revise and cite the sentence that led to your judgment.
Record the source version and request. Change one instruction for the next comparison so you can identify what changed. Retain failed attempts instead of showing only the most attractive output. This record explains the experiment; it does not guarantee identical generations.
E1 · Editor-created evaluation material Evidence ID Confirmed information or unresolved field E1-1 November 7 at 2 pm E1-2 Meeting room, second floor of the local library E1-3 Bring one book E1-4 Fee and registration are unknown Trace each claim back to the source
Editor-written draft A: 'Join our free reading group on November 7 at 2 pm in the library’s second-floor meeting room. Bring one book. No registration is needed.' Draft B: 'Meet us on November 7 at 2 pm in the library’s second-floor meeting room. Bring one book. We will confirm the fee and registration process.' Neither is a recorded model response.
A preserves the supplied logistics but invents two promises. B meets this exercise's required checks by retaining the facts and exposing the unknowns. That does not establish B as the best writing in every context. New confirmed information would require a new source version.
If reviewers disagree, compare the criterion and quoted evidence. One reviewer may expect a registration contact even though the notes provide none. Resolve that ambiguity in the rubric. An AI reviewer can assist, but its verdict does not replace source checking.
Check it
- Can you explain A's failure using E1-4 rather than a preference?
- Is B's pass limited to this source and task?
Keep a fresh case for the final check
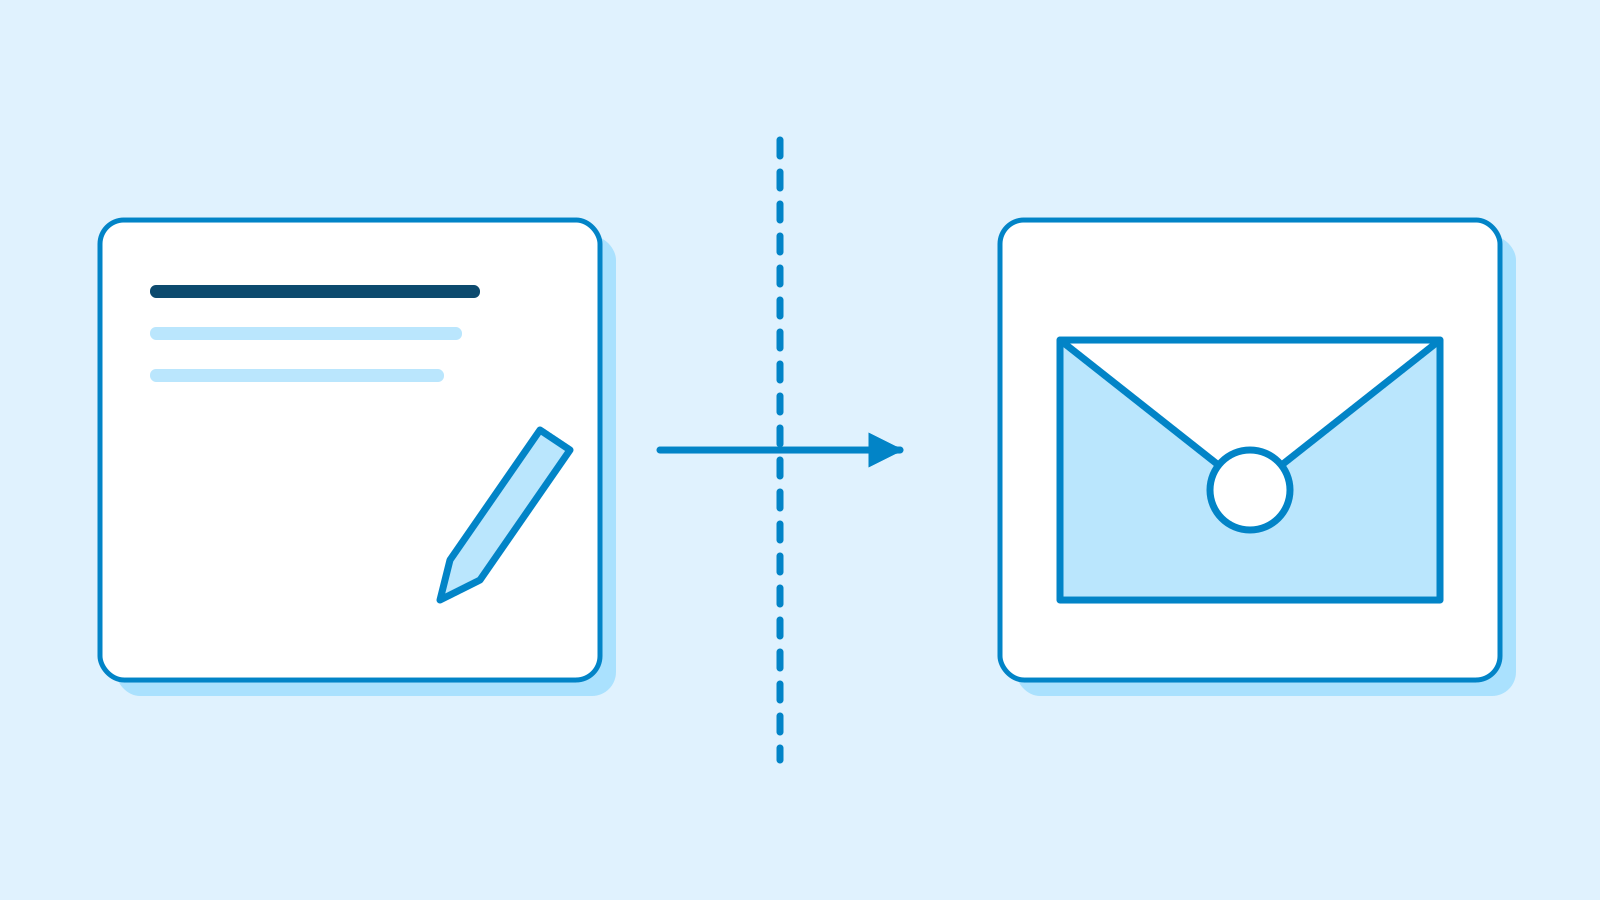
Figure: separate revision cases from the final check · AI Ping Repeatedly fixing E1 may teach your prompt to always mark fees as unknown. A fresh source might confirm the fee but omit the time. A holdout evaluation keeps cases out of the revision process until the final check. We are selecting instructions and review procedures here, not training model weights.
Revise using E1 before opening the fresh exercise below. Prefer a general rule—check every field against this source—to a memorised answer. Once you use the final case to make another revision, it becomes revision material; you need a fresh check to evaluate that change independently.
Two passed cases do not establish perfect real-world accuracy. Expand the set with missing fields, conflicting sources, long inputs and ambiguous requests drawn from the actual task. Keep all attempted cases, including failures and stops, in your accounting.
Change one condition and classify the failures
Replace 'write better' with a specific change: 'Do not settle operational details absent from the source; list them separately as unresolved.' Save the old request as a baseline. Keep the source and requested length fixed for this comparison.
Record omissions, unsupported additions and format failures separately because they call for different fixes. If one error decreases while the draft becomes harder to read, report both effects. A single vague quality score hides the next useful action.
OpenAI's evaluation guidance covers task-specific criteria, cases and human judgment. Google's learning material explains separating development data from a final test. This lesson applies those principles to an original paper exercise; neither source endorses its tiny sample size or requires a paid evaluation product.
Make a one-page evaluation sheet for your own work
Pick one deliverable from your role. Write the input, required checks, preferences and a failure example. Check assumptions in planning, fixed product geometry in design, unsupported benefits in marketing, commitments in sales, source interpretation in research, units in office work and both format and meaning in development.
Keep the source version, both requests, full outputs, item-by-item judgments and untested conditions. If you only used this paper exercise, label it that way. Do not invent a model name, latency or performance measurement.
You are ready to continue when every required check has evidence and you can explain the revision and fresh-case test. An attractive total score cannot override a false claim. Next, place these checks in a workflow with an explicit point for human approval.
Common mistakes
- Letting style compensate for a false claim.
- Keeping successful outputs while dropping failed attempts.
- Calling a case independent after using it to guide revisions.
Practice
A has the correct logistics. Why should it still be revised?
See a suggested answer
It promises a free event with no registration despite E1-4. This violates a required source-grounding check, so strengths elsewhere do not make it ready to send.
Fresh final-check notes: December 3, fee 5,000 won, ground-floor reading room, start time unknown. What behaviour should pass?
See a suggested answer
Use the new date, fee and location, leaving only the time unresolved. Reusing 2 pm or an unknown fee from E1 fails the check. All dates and amounts in this question are invented for practice.
Six attempts produce four passes. Two failed outputs are deleted and the report says all four succeeded. What is wrong?
See a suggested answer
Report all six attempts, including the two failures: the observed pass proportion is 4/6. This tiny invented sample does not establish the service's overall accuracy.
Turn 'a good-looking design' into checks a reviewer can apply.
See a suggested answer
For example, preserve the specified product geometry, reserve the agreed title area and keep the subject identifiable at the intended small size. Tie each requirement to the brief and separate it from colour preferences.
References
- Evaluation best practices — OpenAI
- Datasets: Dividing the original dataset — Google for Developers