Measure an AI pilot and decide when to stop
Count review and repair as well as generation. Compare fictional task records with a baseline and decide whether to continue, revise or stop.
About 19 min readingAs of Oct 2026
By the end of this guide
- Compare full task time, including review and repair, with a baseline.
- Judge serious errors separately from speed gains.
- Write a plan with change records, stop conditions and a rollback procedure.
Who this is for
- You need to explain the practical effect of AI use to a team.
- You have a small pilot and need to decide its next scope.
What you need
- Complete the evaluation and workflow lessons.
- Use the table with a calculator or spreadsheet. Every value is fictional practice data, not an observed business result.
This lesson’s terms, in plain language
Read the short meanings here. Open a term for a fuller explanation and example.
- baseline
- The existing result or process used as the starting point for a comparison.
- hypothesis
- An unverified idea that can be investigated through observation or a test.
- rollback
- Returning to a previously verified version or process after a problematic change.
- fallback
- An alternative path when the current process cannot finish the task.
- workflow
- A sequence of work with conditions for moving between steps.
Step by step
A fast draft may still take a long time to finish
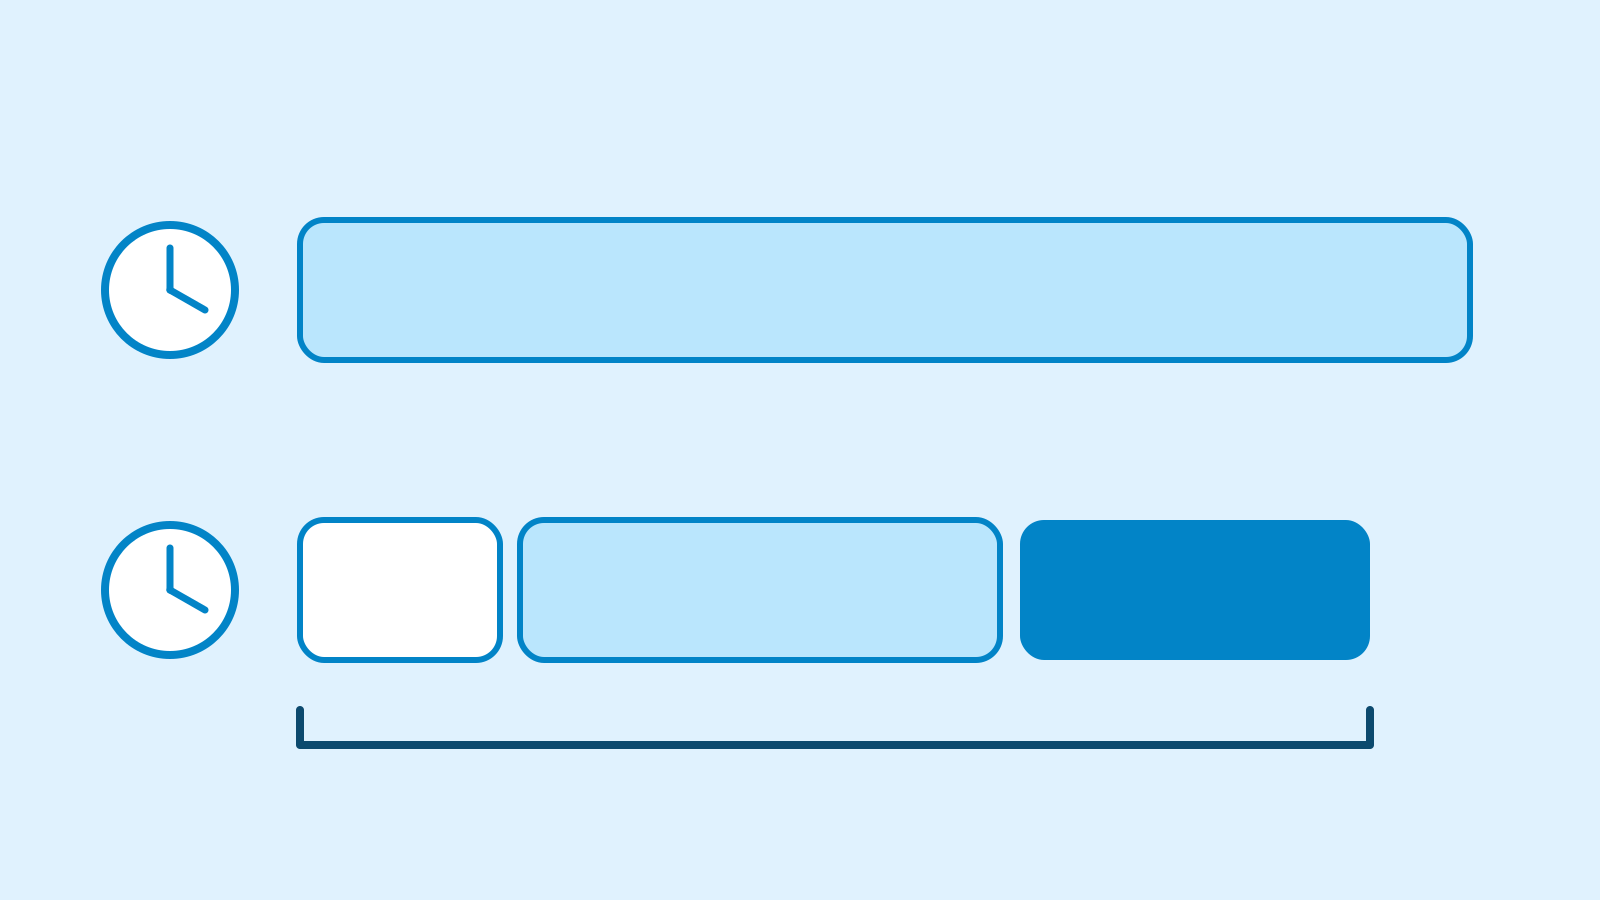
Suppose a report used to take 20 minutes and an AI draft appears in two. If checking takes eight more minutes and repair takes six, completion takes 16—not two. These are invented numbers. Compare the point at which the same quality standard is met.
A baseline is the starting method used for comparison. Match task type, difficulty, scope and completion criteria before comparing times. Distinguish active human work from elapsed waiting time instead of adding incompatible measurements.
Design work includes revisions, sales work includes proposal checks, research includes source verification and development includes testing and repair. Also account for work shifted to someone else; a fast draft can create a slow review queue.
Check units and totals before interpreting the result
Figure: include all work needed for completion · AI Ping The table contains five invented document tasks. Values are minutes of active human work. Input/draft includes preparation, requesting and handling the draft. Waiting time and tool charges are excluded; state that scope before interpreting the numbers. The downloadable CSV matches the table.
Baseline time totals 100 minutes. New-process row totals are 16, 15, 30, 12 and 20: 93 minutes overall. The difference is seven minutes, or 7% of this fictional baseline. Task C takes five minutes longer, which an aggregate alone conceals.
Do not convert this into a claim that employee productivity increased by 7%. Five invented records omit broader costs, quality differences and learning effects. A time record also does not prove that the output met the rubric; check quality separately.
Fictional practice records · active human minutes Task Baseline Input/draft Review Repair A 20 2 8 6 B 18 3 8 4 C 25 4 12 14 D 17 2 7 3 E 20 3 9 8 Total 100 14 44 35 Do not let speed hide a consequential error
A faster proposal is unusable if it promises a nonexistent capability. Put rubric results beside time records. A failed task that ends quickly is not an efficiently completed task. Keep failures and repair costs visible.
Define a stop condition before seeing results. For this exercise, an unsupported customer promise stops external use until the review process is fixed. This is an instructional condition, not a universal numerical standard; real criteria depend on consequences and responsibilities.
Investigate why C needed extensive repair: conflicting evidence, excessive scope or a missing check. Distinguish an observed failure from a hypothesis about its cause. Change one relevant condition and test new cases instead of assuming a different product will solve it.
Recheck the work when sources or instructions change
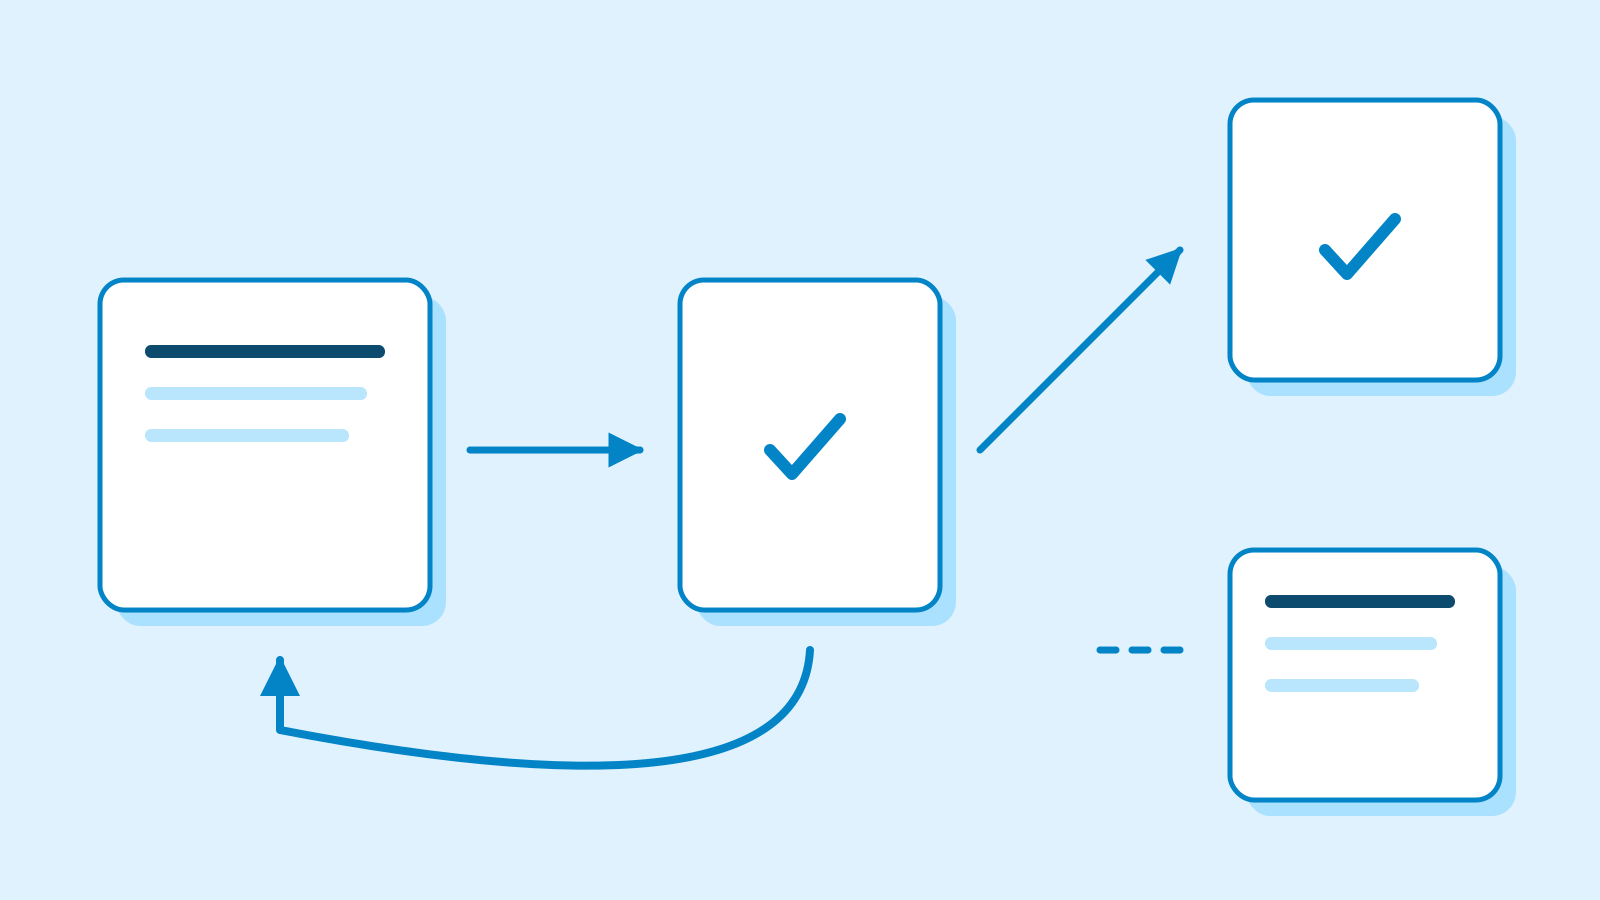
Figure: test a changed version and retain a route back · AI Ping Passing an evaluation once does not cover changed sources, instructions or tools. Record what changed, why, which cases were checked and what remains untested. Update expected answers when authoritative source facts change.
Rollback means returning to a previously verified process or version. Retain its records and assign a recovery owner. If old source facts are obsolete, the safe fallback may be a manual check of current evidence, not an old automatic answer.
Restoring a process does not undo an already delivered mistake. You still need to identify affected work and assign correction. Our exercise uses only fictional records; write that path without sending anything. Plan recovery alongside benefits, before expanding scope.
Choose continuation, revision or stopping from the evidence
The time table supports further investigation, not an organisation-wide benefit claim. Representativeness, equal quality, tool charges and setup costs remain unresolved. State the observed seven-minute difference separately from any proposed broader effect.
If revising, name one change and a fresh test. Evidence that conflicting source versions caused C's repair burden would justify an intake version check. Define success before seeing the next result, retaining unfavourable cases.
If continuing, specify a narrow scope: perhaps internal notices with approved evidence, while ambiguous customer proposals remain manual. Deeper expertise includes explaining where automation should stop. Add newly observed failures to future evaluation cases.
Write a one-page adoption decision
Put your rubric and workflow beside the time calculation. Check the total by hand, then write four fields: observation, causal hypothesis, decision and missing evidence. Ninety-three minutes is an arithmetic result; the cause of C's repair time is not in the table.
Your plan should specify scope, required checks, measurement method, stop condition, fallback and owner. This is a fictional process-improvement exercise, not a basis for ranking employees. Leave unmeasured quantities explicitly unmeasured.
Continue to your role's advanced project when comparison scope is consistent, review and repair are included and serious errors cannot be traded for speed. Explain the next test and recovery path. The project combines these lessons and introduces a new condition after your first draft.
Common mistakes
- Comparing generation time with full baseline task time.
- Presenting a small fictional sample as a customer result.
- Relaxing a predefined stop condition after seeing poor results.
Practice
What is the new-process total and its difference from baseline?
See a suggested answer
14 + 44 + 35 = 93 minutes, seven fewer than the 100-minute baseline, or 7% of that fictional baseline. This is not a real-world productivity measurement.
If setup adds a one-off 30 minutes, did these five tasks save time overall?
See a suggested answer
The total becomes 123 minutes, 23 more than baseline. The 30-minute setup value is invented too; future savings require further observation rather than extrapolation.
Time decreases, but an unsupported customer promise remains. Has the pilot met its stop rule?
See a suggested answer
That triggers this exercise's stop condition. Pause external use and fix grounding and review. Speed and required quality are separate decisions.
The previous source is obsolete, but the new workflow must be rolled back. What should replace it?
See a suggested answer
Use a manual process that verifies current evidence instead of reviving obsolete answers. Assign separate ownership for identifying and correcting any errors already delivered.
References
- Errors + Graceful Failure — Google PAIR
- Evaluation best practices — OpenAI