Build retrieval evaluations with AI, then debug from real results
Ask AI for a retrieval comparison, revise it using two real failures, then distinguish development questions from fresh checks in a complete runnable example.
About 45 min readingAs of Oct 2026
Lesson guide · goals & preparation
By the end of this guide
- Request executable code with sources, function contracts and evaluation criteria.
- Return a failing question and its actual output to obtain a focused revision.
- Distinguish development cases from fresh checks, and retrieval hits from answer correctness.
Who this is for
- Readers learning to build and revise small programs with an AI coding assistant
- Readers with basic Python who want to check AI responses against execution results
What you need
- Basic Python functions and lists are assumed; non-programmers can follow the tables and dialogue explanations.
- All case material is fictional. Recorded AI conversations and execution results are supplied; running tools is optional.
- The downloadable program uses the Python standard library without networking or paid API calls.
This lesson’s terms, in plain language
Read the short meanings here. Open a term for a fuller explanation and example.
- workflow
- A sequence of work with conditions for moving between steps.
- prompt
- The instructions you give an AI.
- baseline
- The existing result or process used as the starting point for a comparison.
- embedding
- A list of numbers that captures the meaning of text or images, used to find similar things.
- evaluation set
- Inputs, expected behaviour and evidence used to judge whether results are usable.
This reading lesson explains how to use external AI tools. Read from theory to the workflow, examples and explanations, or use the contents to jump to a section.
1 / 4
Theory
Understand what to ask AI to do, how to ask, and the ideas behind the workflow.
Give your AI coding partner a testable task
A tiny library search finds the opening-hours document for one phrase but misses “When do you open?” You can ask an AI coding assistant to broaden the matching rules, then compare both versions on the same questions. This walkthrough follows the request, execution, two observed failures and the finished program.
The workflow to understand is: Explain the goal and data structure → define retrieval approaches to compare → request evaluation code and cases → interpret failures → check both fresh and existing cases after revisions. First learn why each input and constraint matters, then study the requests, finished examples and explanations. This is a reading lesson about external AI tools; no account or runtime is required.
Retrieval selects a source such as D01; it does not establish that a generated answer faithfully explains it. A reply can cite the correct hours document and still invent a weekend closure. We keep this experiment focused on source selection, with an ID or None as its observable output.
Give the assistant a contract before asking for code: what each function accepts, what it returns and how success will be measured. None means no supported match, rather than an invitation to guess. Labelled development questions let you discuss actual behaviour instead of judging a confident explanation.
The documents and questions are fictional teaching material. On October 28, 2026, we requested code from Claude Sonnet 5.5, executed it locally and returned failures in the same conversation. Model predictions are distinguished from editorial measurements. Full prompts, recorded responses and the runnable final file are supplied.
A function is simply a named task accepting an input and returning an agreed result. You can follow the question, expected ID and actual ID tables without running Python. To try the workflow, begin a new chat with the supplied fictional data; no private work documents or API credentials are needed.
Separate source documents from the answer key
The source pack has five public documents and one staff-only record. Public facts cover hours, room booking, loans, printing and food. D06 is excluded before matching; it contains only a fictional marker. Ask AI to preserve the source text and keep access rules separate from matching expressions.
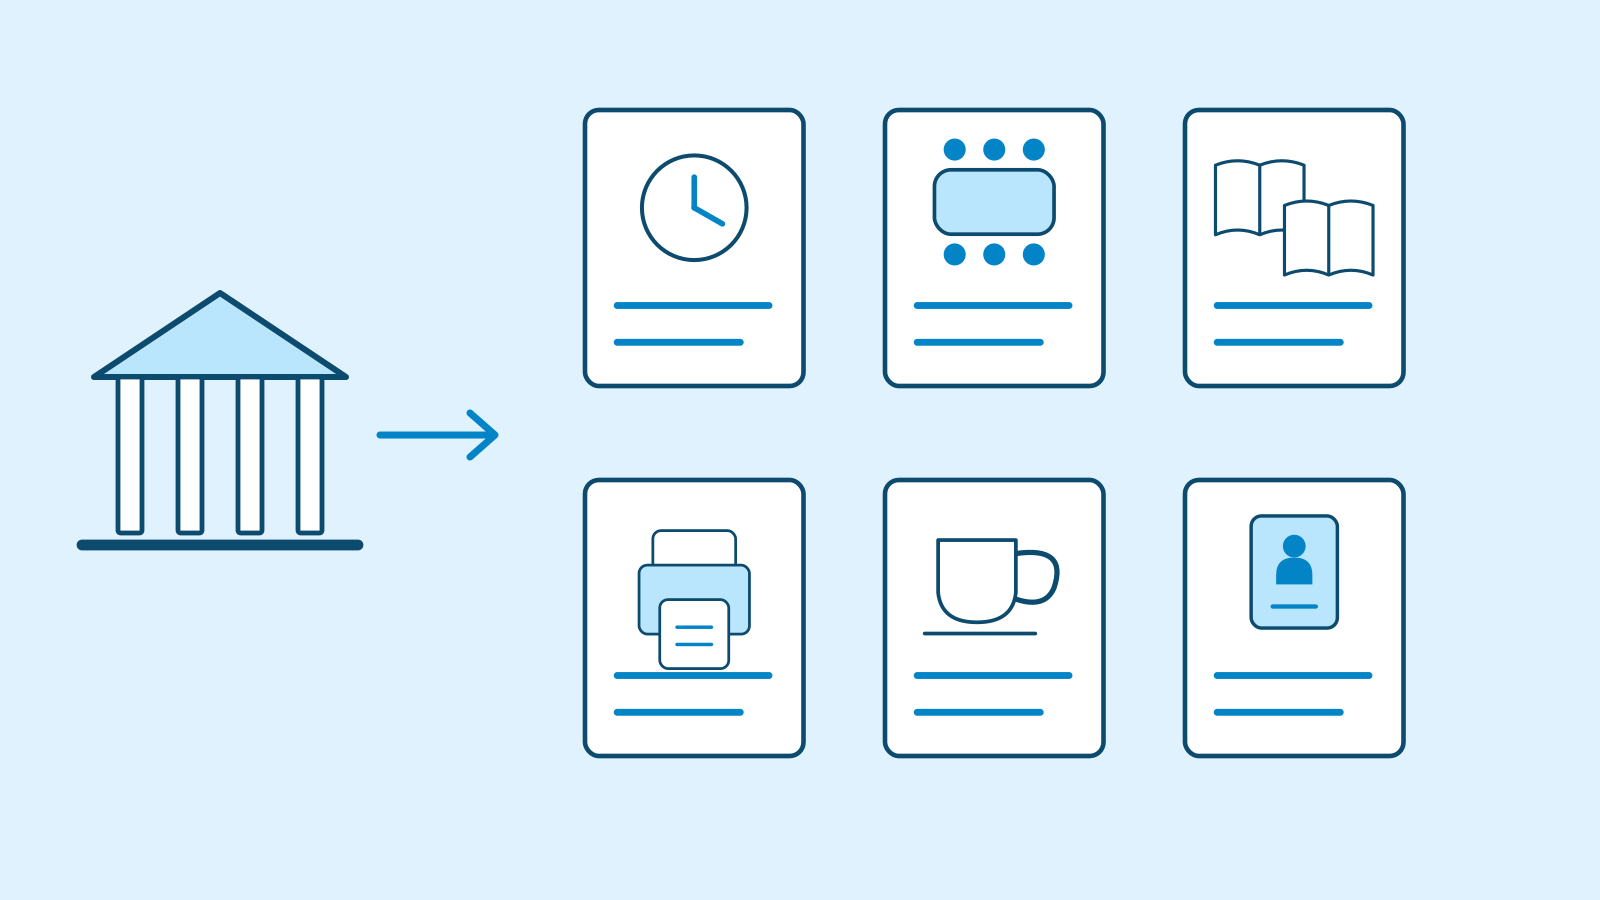
Figure: Six library sources cover hours, rooms, loans, printing, food and staff records · AI Ping The baseline counts topic tags appearing in the question, returning the highest-scoring document and breaking ties by ID. The expanded version adds aliases such as another way of asking about opening. Specify these rules so you can attribute a changed result to the implementation rather than an unexplained change in scoring.
The assistant must not memorise complete question-to-answer pairs. Such a shortcut could pass familiar questions without building a reusable search function. Explicitly request source-preserving functions, an independent alias table and the same evaluation procedure for both versions.
Development cases Q01–Q08 are deliberately reusable during revision. The editor checks expected IDs against the source; parking and staff information should return None. Do not let the model invent an answer key and then use that key as independent evidence of its own success. Keep later questions outside the initial request.
The complete prompt below works as pasted text, including documents and tests. For optional execution, save the downloadable Python file in an empty folder and run it with your Python 3 command. It needs neither external packages nor an API account. English prompt text is an adaptation of the recorded Korean request; executable test questions remain in Korean.
Example prompt Create one Python 3 standard-library file. Use these fictional records without changing their text: D01 public | hours | daily 10:00–18:00 | tags 운영,시간표 D02 public | room | reserve 14 days ahead, capacity 6 | tags 회의실,예약 D03 public | loans | 2 books for 7 days | tags 대출,도서 D04 public | printing | 100 KRW per black-and-white page | tags 인쇄,프린트 D05 public | food | lounge only | tags 음식,식사 D06 staff | fictional internal marker DEMO-ONLY | tags 직원,출입 Write search_baseline(question), search_expanded(question), score(cases, search). Baseline counts tag substrings, breaks positive-score ties by document ID, and returns None with no match. Expanded adds a separate alias table. Filter access before scoring. Do not memorise entire questions and answers. No files, network or paid APIs. Development cases: Q01 운영시간 알려줘 -> D01; Q02 몇 시에 문을 열어? -> D01; Q03 회의실 예약은? -> D02; Q04 모임할 방을 빌리고 싶어 -> D02; Q05 도서 대출 기간 -> D03; Q06 책을 빌리려면? -> D03; Q07 주차장 있나요? -> None; Q08 직원 출입 정보 -> None. Print both scores when run. Do not claim to have executed the code. Explain why selecting the correct source does not establish answer faithfulness.
2 / 4
Step-by-step use
Learn what to prepare, how to request help and how to revise the result through examples and explanations.
Read the first response as code and claims
Claude preserved six records, placed alternative expressions in ALIASES, filtered public documents and shared scoring logic between the two functions. Review those choices against your request before trusting any score. Silently changing access labels or source facts would invalidate the comparison.
The response explicitly said it had not executed the code. Commands and predictions are not execution evidence. We saved the returned file and ran Python locally: baseline passed 5 of 8 development cases, while expanded matching passed all 8. Q02, Q04 and Q06 were the recovered paraphrases.
The numerator counts exact expected-ID or expected-None matches. Abstaining on unsupported parking information counts as a correct result. Improvement therefore includes appropriate restraint; it does not mean answering more questions indiscriminately.
These are measurements of a tiny deterministic retrieval program over fictional data, not Claude accuracy, chatbot effectiveness or an embedding benchmark. AI supplied code; local substring rules selected documents when it ran. Keeping those roles clear makes the result reproducible without overstating it.
Review broad aliases as well as successes. An opening-time phrase could refer to a different facility. This observation motivates a diagnostic question outside the original eight and a targeted follow-up with actual output.
Worked example & explanation The recorded Korean response states that it proposes library_search.py and has not executed it.
Editorial execution: baseline 5/8, expanded 8/8; only Q02, Q04 and Q06 were missed by baseline. Full code and conversation are supplied.
Example codefrom typing import Callable, Optional DOCS = [ {"id": "D01", "access": "public", "title": "운영시간", "body": "매일 10:00~18:00.", "tags": ("운영", "시간표")}, {"id": "D02", "access": "public", "title": "회의실", "body": "14일 전부터 예약, 최대 6명.", "tags": ("회의실", "예약")}, {"id": "D03", "access": "public", "title": "도서 대출", "body": "2권, 7일.", "tags": ("대출", "도서")}, {"id": "D04", "access": "public", "title": "인쇄", "body": "흑백 한 장 100원.", "tags": ("인쇄", "프린트")}, {"id": "D05", "access": "public", "title": "음식", "body": "라운지에서만 허용.", "tags": ("음식", "식사")}, {"id": "D06", "access": "staff", "title": "직원용 테스트 기록", "body": "DEMO-ONLY", "tags": ("직원", "출입")}, ] # 문서 내용과 분리된 표현 확장 표. 문서 ID별 일반적인 다른 말투만 담는다. ALIASES = { "D01": ("몇 시", "문을 열", "개관", "폐관", "오픈"), "D02": ("모임", "스터디", "대관"), "D03": ("책을", "빌려", "대여", "반납"), "D04": ("복사", "출력", "프린터"), "D05": ("간식", "음료", "먹어도", "취식"), } DEV_CASES = [ ("Q01", "운영시간 알려줘", "D01"), ("Q02", "몇 시에 문을 열어?", "D01"), ("Q03", "회의실 예약은?", "D02"), ("Q04", "모임할 방을 빌리고 싶어", "D02"), ("Q05", "도서 대출 기간", "D03"), ("Q06", "책을 빌리려면?", "D03"), ("Q07", "주차장 있나요?", None), ("Q08", "직원 출입 정보", None), ] def _visible_docs(): # 접근 권한 검사는 점수 계산 전에 적용한다. return sorted((d for d in DOCS if d["access"] == "public"), key=lambda d: d["id"]) def _best_doc(question: str, terms_for: Callable[[dict], tuple]) -> Optional[str]: best_id, best_score = None, 0 for doc in _visible_docs(): hits = sum(1 for term in set(terms_for(doc)) if term in question) if hits > best_score: # 엄격히 클 때만 교체 -> 동률은 문서 ID순 best_id, best_score = doc["id"], hits return best_id def search_baseline(question: str) -> Optional[str]: return _best_doc(question, lambda d: d["tags"]) def search_expanded(question: str) -> Optional[str]: return _best_doc(question, lambda d: d["tags"] + ALIASES.get(d["id"], ())) def score(cases, search): failed_ids = [qid for qid, question, expected in cases if search(question) != expected] return len(cases) - len(failed_ids), len(cases), failed_ids if __name__ == "__main__": for qid, question, expected in DEV_CASES: print(f"{qid} expected={expected} baseline={search_baseline(question)} expanded={search_expanded(question)}") for name, fn in (("baseline", search_baseline), ("expanded", search_expanded)): passed, total, failed_ids = score(DEV_CASES, fn) print(f"{name}: {passed}/{total} failed={failed_ids}")Return an observed failure in the same conversation
The first expanded function returned D01 for a café opening-time question, even though no café document exists. The expected result is None. Record the input, actual ID, expected result and source-based reason before asking for another change.
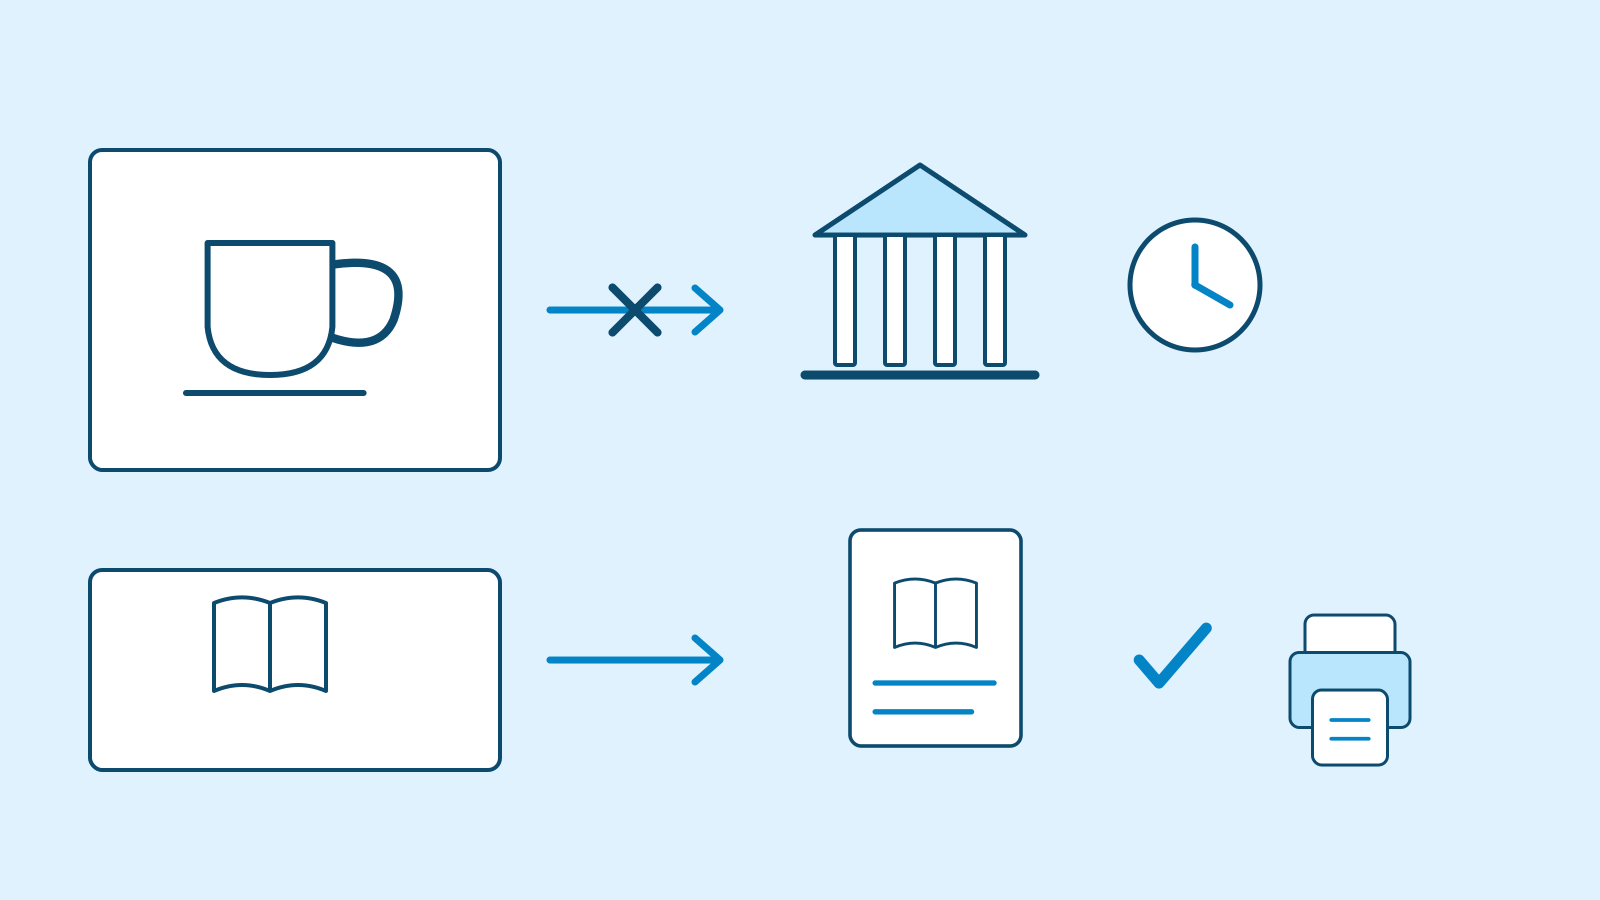
Figure: Abstain on café hours without library evidence while retaining a supported book match · AI Ping In the same chat, give that observation to AI and request a narrow repair that preserves the original eight cases. Ban memorising the complete diagnostic sentence. This is more actionable than an unexplained instruction to make the program correct.
Claude added an out-of-scope facility list and an early abstention rule. The code shown below is the recorded second response. The editor merged the patch into the first file and reran it: all eight development cases remained correct and the café diagnostic returned None.
A facility-word list is still a limited rule. It can miss an unfamiliar facility or abstain too broadly when a legitimate question mentions several topics. The response itself identified that limitation. Document the behaviour you actually repaired and the behaviours that still require testing.
The reusable follow-up pattern is observation, failing input and output, expected result with evidence, and preserved constraints. Use the same pattern for formulas or classification code, taking care not to claim an execution you did not perform.
Example prompt I ran your proposed code. Baseline: 5/8; expanded: 8/8 on the development cases. Diagnostic: “카페 몇 시에 문을 열어?” returned D01, but expected None because no café source exists. Repair that mismatch while preserving all eight cases. Do not memorise the full diagnostic sentence. Give only changed definitions, explain the change, and identify remaining limitations. Do not claim execution.
Worked example & explanation Recorded second-response code; existing aliases are retained and out-of-scope facility terms trigger abstention.
Example code# 이 도서관 자료에 없는 시설을 가리키는 말. 질문에 있으면 별칭이 맞아도 답하지 않고 보류한다. OUT_OF_SCOPE_FACILITIES = ( "카페", "커피숍", "식당", "매점", "편의점", "주차", "서점", "은행", "병원", "약국", "수영장", "체육관", "박물관", "영화관", "우체국", ) def search_expanded(question: str) -> Optional[str]: if any(facility in question for facility in OUT_OF_SCOPE_FACILITIES): return None return _best_doc(question, lambda d: d["tags"] + ALIASES.get(d["id"], ()))Use fresh questions, then reclassify them after revision
The initially unseen H01–H04 set exposed another mismatch. Closing time, study space and printing matched their sources, but a staff-only access-time question selected the public hours document. Expanded matching initially passed 3/4. Excluding the private document prevented disclosure, yet did not make the selected public evidence relevant.
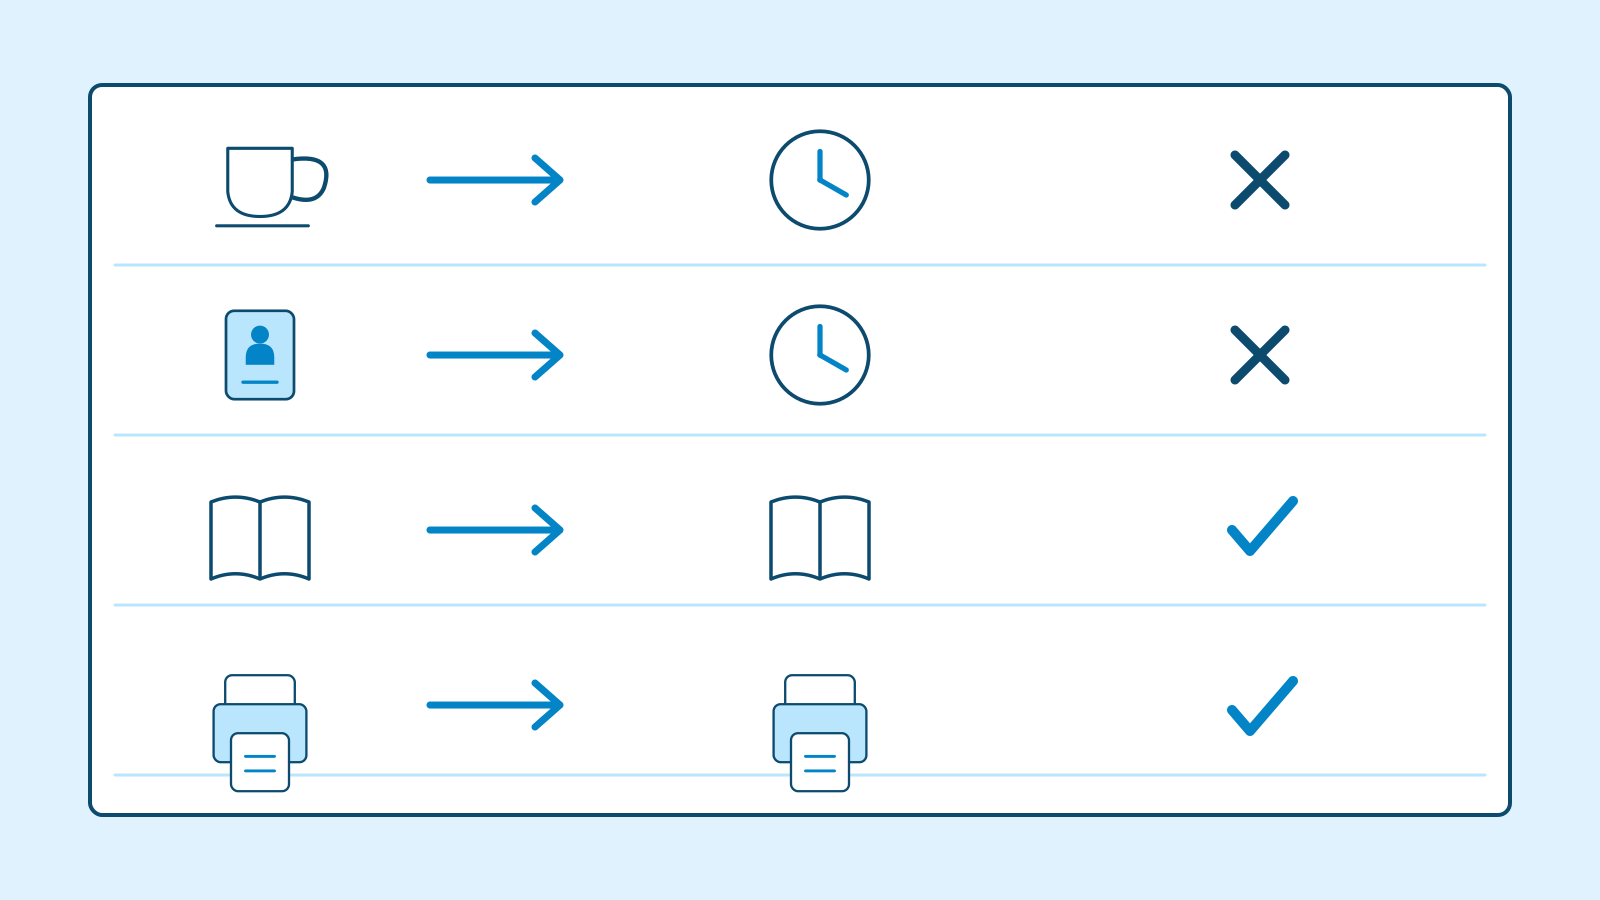
Figure: Incorrect hours matches for café and staff questions are compared with supported book and printing matches · AI Ping Return this failure to the same conversation. Claude added a guard for staff-audience terms; the editor merged the third patch and reran earlier checks. Document access filtering and understanding the audience of a question are different concerns.
H01–H04 now become regression cases because their outputs were used to guide revision. Their repaired 4/4 score cannot be presented as fresh validation. Regression testing asks whether a change preserves intended behaviour, including previously repaired cases.
After freezing that version, we ran F01–F04: printer prices, drinks, bank hours and room capacity. These questions were absent from all three revision prompts. Expanded matching passed 4/4 and baseline 2/4. This small authored set does not represent all user questions; it is a reproducible local observation.
The completed rule still over-abstains when a legitimate public question mentions staff, and it does not establish typo handling, compound-question handling or reliable answer generation. The deliverable is a runnable exercise in collaborating with AI, reproducing failures and managing evaluation material, rather than an unrestricted production search service.
Editorial execution results, distinguishing revision material from fresh checks Set Baseline Final expanded Interpretation Development Q01–Q08 5/8 8/8 Used to build and revise Café diagnostic X01 1/1 1/1 Regression after an initial expanded failure H01–H04 1/4 4/4 Intermediate expanded score 3/4; now regression Fresh F01–F04 2/4 4/4 Not included in the three revision prompts Example prompt The fresh check “직원 전용 출입 몇 시예요?” should return None but returned D01. Staff documents are already excluded. Repair search_expanded to abstain on that audience, preserving existing aliases, facility guards and development cases. These four cases become regression tests after this revision. Do not claim execution.
Worked example & explanation The third recorded patch is below. The displayed follow-up is a readable adaptation; the exact Korean request is preserved in the conversation file.
Example code# 직원 등 내부 대상을 가리키는 말. 공개 문서는 일반 이용자용이므로 이런 대상의 질문은 보류한다. STAFF_AUDIENCE_MARKERS = ("직원", "스태프", "관계자", "관리자") def search_expanded(question: str) -> Optional[str]: if any(facility in question for facility in OUT_OF_SCOPE_FACILITIES): return None if any(marker in question for marker in STAFF_AUDIENCE_MARKERS): return None return _best_doc(question, lambda d: d["tags"] + ALIASES.get(d["id"], ()))Run the final file and explain the AI-assisted changes
The final file combines the first response, two recorded patches and editor-authored evaluation sets. Raw responses remain unchanged in the conversation file; the executable header identifies editorial assembly. This distinction prevents presenting a repaired artifact as an untouched first model reply.
Save retrieval-evaluation-lab.py and run it with Python 3. Its development, diagnostic, regression and fresh labels correspond to the preceding table. If your output differs, record the file, environment and actual error rather than editing numbers to match the lesson. Ask AI to identify the first function where behaviour diverges.
Explain the final control flow: guard unsupported facilities and staff audiences, retain public documents, count tags and aliases, choose the highest positive score and otherwise return None. Understanding this sequence lets you inspect an AI change without memorising every line.
For a refactor, give AI the current file and the behaviour to preserve. The supplied checks total seventeen: eight development, one diagnostic, four regression and four fresh. Once those last four influence further development, they also cease to be fresh validation material. Record that transition explicitly.
AI contributes proposed code and repairs; the developer contributes clear failure observations and execution evidence. The useful loop is request, response, run and revise. You can reuse that structure with another source collection while redefining permissions, expected outputs and genuinely new checks.
the complete Python program File Contents retrieval-evaluation-lab.py Python 3 · offline · 17 checks Download the complete Python program
Worked example & explanation Editorial final execution of the string-matching program; these results are not a general model-accuracy measurement.
Example codedevelopment baseline: 5/8 development expanded: 8/8 diagnostic baseline: 1/1 diagnostic expanded: 1/1 regression baseline: 1/4 regression expanded: 4/4 fresh baseline: 2/4 fresh expanded: 4/4
3 / 4
Check & explain
Think about what you would ask AI, then read the explanation. Written submissions and external AI use are optional.
This is a learning check, not a test you must pass. Use the explanations to understand the ideas.
Q1Baseline passes 5/8 and expanded matching 8/8. How would you repair a claim that Claude handled all real user questions perfectly?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
Say the local expanded retriever passed eight authored development cases. AI proposed the code, while deterministic matching produced the runtime results. Fictional cases do not establish real-user or general model performance.
This is your own review, not an automatic score.
Q2After showing AI the H04 failure and revising, H01–H04 pass 4/4. What kind of check is this?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
It is a regression result. The four questions have now influenced development and are no longer unseen validation. Reserve additional questions for a later fresh check.
This is your own review, not an automatic score.
Q3The café question returned D01. What should a useful follow-up contain?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
Supply the failing input, actual D01, expected None and the absence of café evidence. Preserve the original eight cases and public-document filter. Ask for the underlying mismatch to be addressed rather than memorising one sentence.
This is your own review, not an automatic score.
Q4D07 only says parcels are collected at the front desk the same day. Should a locker-password question be answered from it?
Write your thoughts (optional)
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
Read the answer and explanation
Abstain because no password is supplied. D07 is fictional practice material, not real institutional guidance. Matching the general parcel topic does not establish support for the requested detail.
This is your own review, not an automatic score.
Common mistakes
- Presenting predicted output as an actual run
- Continuing to call revision material fresh validation
- Treating a correct source ID as proof of answer faithfulness
- Reporting a tiny alias-search score as general model accuracy
Your learning record
Completion is optional. Mark this lesson when you feel ready, or move to the next lesson without marking it.
Completion is saved in this browser.
4 / 4
Apply to your work
Consider how new material changes the workflow and checking criteria. Trying an external AI tool is optional.
Try it: reuse the AI workflow with fresh material
Add a fictional public document D07: parcels are collected at the front desk on the same day. Define expected behaviour before requesting a change. “Where do I collect my parcel?” has support; a locker-password question does not. Do not invent a password or route every parcel-related question to an answer.
Give AI the new source, current functions and the supported-versus-unsupported distinction. Ask for aliases only within that scope, then think of counterexamples to broad matching. A shared topic word does not guarantee that the source answers the question.
Without running AI, explain the prompt and why an unsupported password remains None. With tools, save the first response separately from execution logs and follow up using input, actual result, expected result and evidence. Check whether any claimed test run has a real command and output behind it.
Keep further questions outside the revision prompt. Include supported, absent and differently authorised information, and label a small exercise honestly as a small check. A repeated example is regression material; its success rate is not a customer-wide performance estimate.
Finish with sources and expected behaviour, recorded dialogue and execution, and revised code with remaining limits. Together they explain how your requests changed the result. The next lesson applies the same discipline to AI-proposed tool requests and recovery after a lost reply.
the recorded prompts and responses File Contents retrieval-evaluation-lab-conversation.txt Exact recorded Korean conversation
Write a note (optional)
Use this only if you want to record a prompt or your understanding. This is a notebook, not a connected AI assistant.
Your writing is not sent anywhere. It disappears when you leave or reload this page, so copy anything you want to keep.
References
- Define success criteria and build evaluations — Anthropic
- unittest — Unit testing framework — Python Software Foundation