NVIDIA releases open Nemotron 3.5 models for everything from servers to laptops
3-line summary
- NVIDIA released Nemotron 3.5 Super VL, an open model for agents, plus two Bolt models for PCs and edge devices.
- Super VL has 120 billion parameters and understands images and documents; NVIDIA says it matches its largest reasoning model's accuracy at about a fifth of the size.
- Super VL and Bolt 74B-A9B are available now on Hugging Face and elsewhere, and Bolt E4B follows on October 23.
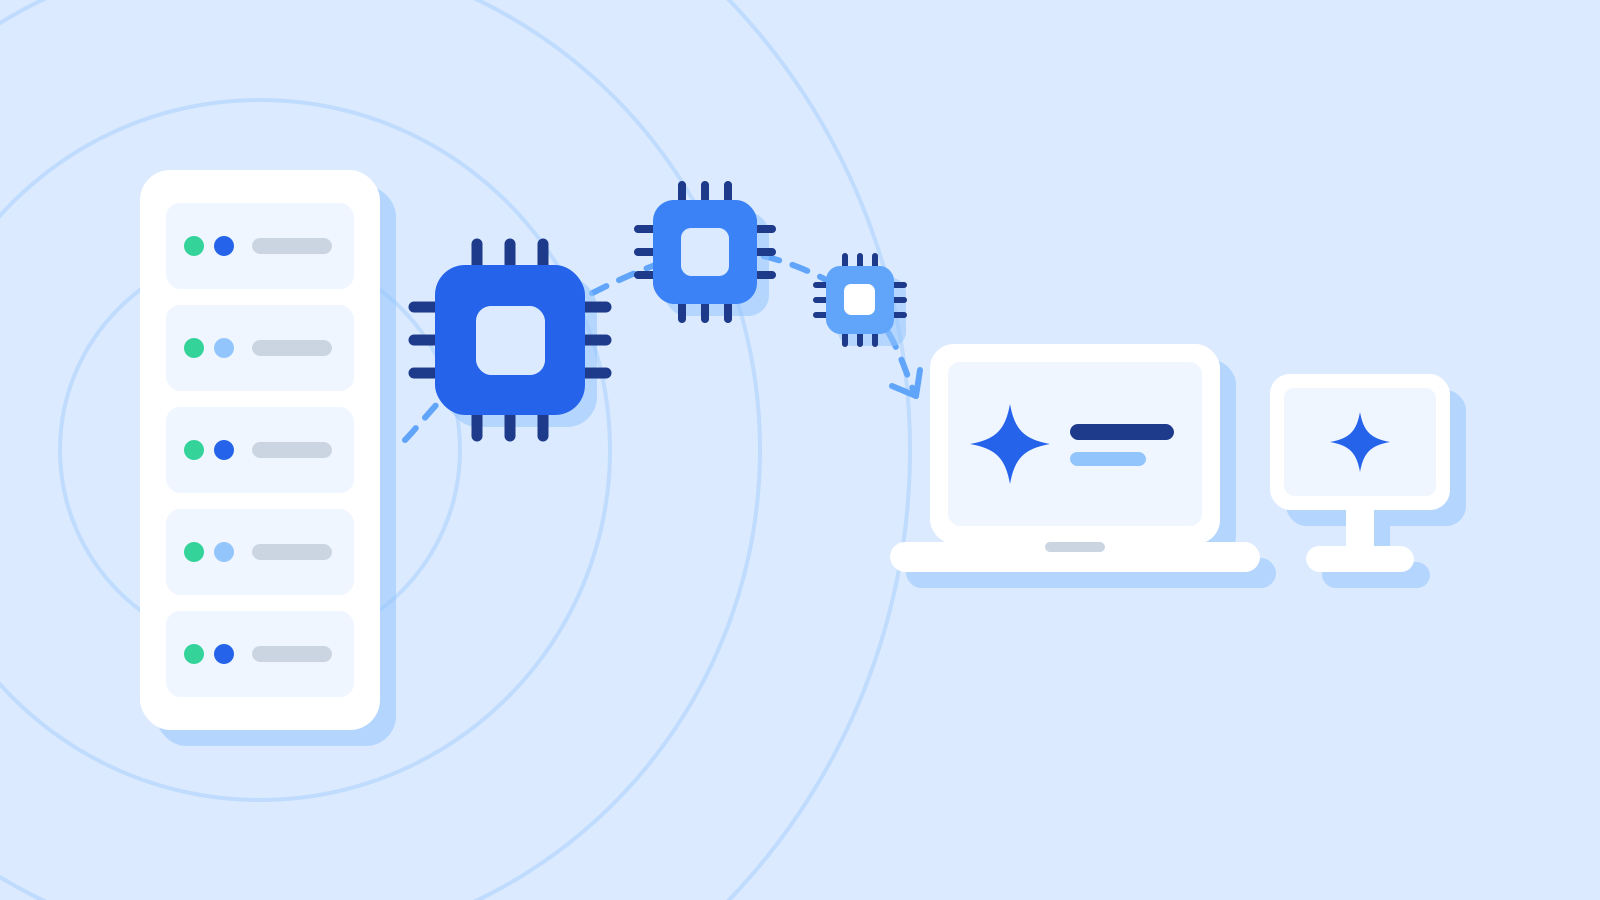
On October 15 NVIDIA released Nemotron 3.5 Super VL, an open model, along with two models for PCs and edge devices: Nemotron 3.5 Bolt 74B-A9B 24GB and Bolt E4B 4GB. The idea is to give every tier where agents run — from big enterprise servers to personal PCs and small edge devices — a matching open model.
Super VL is a 120-billion-parameter multimodal model focused on instruction following, tool use, multi-step business workflows and understanding images, web pages and PDFs. NVIDIA claims it is the fastest open agentic model in its class, five times faster than the next best. It ships with open weights, datasets and training recipes, so companies can post-train it on their own data and run it on their own infrastructure.
Bolt 74B-A9B uses native 2-bit quantization to fit in 24 GB of memory, so personal machines such as RTX Spark laptops and DGX Spark can handle web research, writing or debugging without sending the work to the cloud. It supports llama.cpp, Ollama, LM Studio and vLLM. Bolt E4B 4GB is built for fast conversational agents such as voice assistants.
NVIDIA says Atlassian, CrowdStrike, Perplexity and Salesforce are among the companies integrating or customizing Super VL. The speed and accuracy comparisons rely on benchmarks NVIDIA chose, so real-world performance is worth checking yourself.
Why it matters
By releasing one model family in sizes from server to laptop, NVIDIA gives companies more ways to run agents without sending data off-site. A chipmaker opening up models, data and training recipes also looks like a strategy to widen its GPU ecosystem.
Who it's for
- Developers
- Grab the weights from Hugging Face and run them with vLLM or Ollama. If you have a 24 GB machine, try Bolt 74B-A9B as a local agent.
- Office workers
- If your work involves data that can't leave the company, it's worth telling your IT team that more models can now run in-house.